Applied AI · Trust & Safety · AI Governance
Mateen
Rahmat
Staff AI Evaluation Engineer at LinkedIn.
He designs AI for large-scale decision-making, building the evaluation frameworks, governance standards and human oversight that make its performance measurable and its decisions accurate and reliable.
This is Mateen's AI. It answers from this page and from his own notes, with a link from each answer to its source. If it does not know something about him, it says so.
About
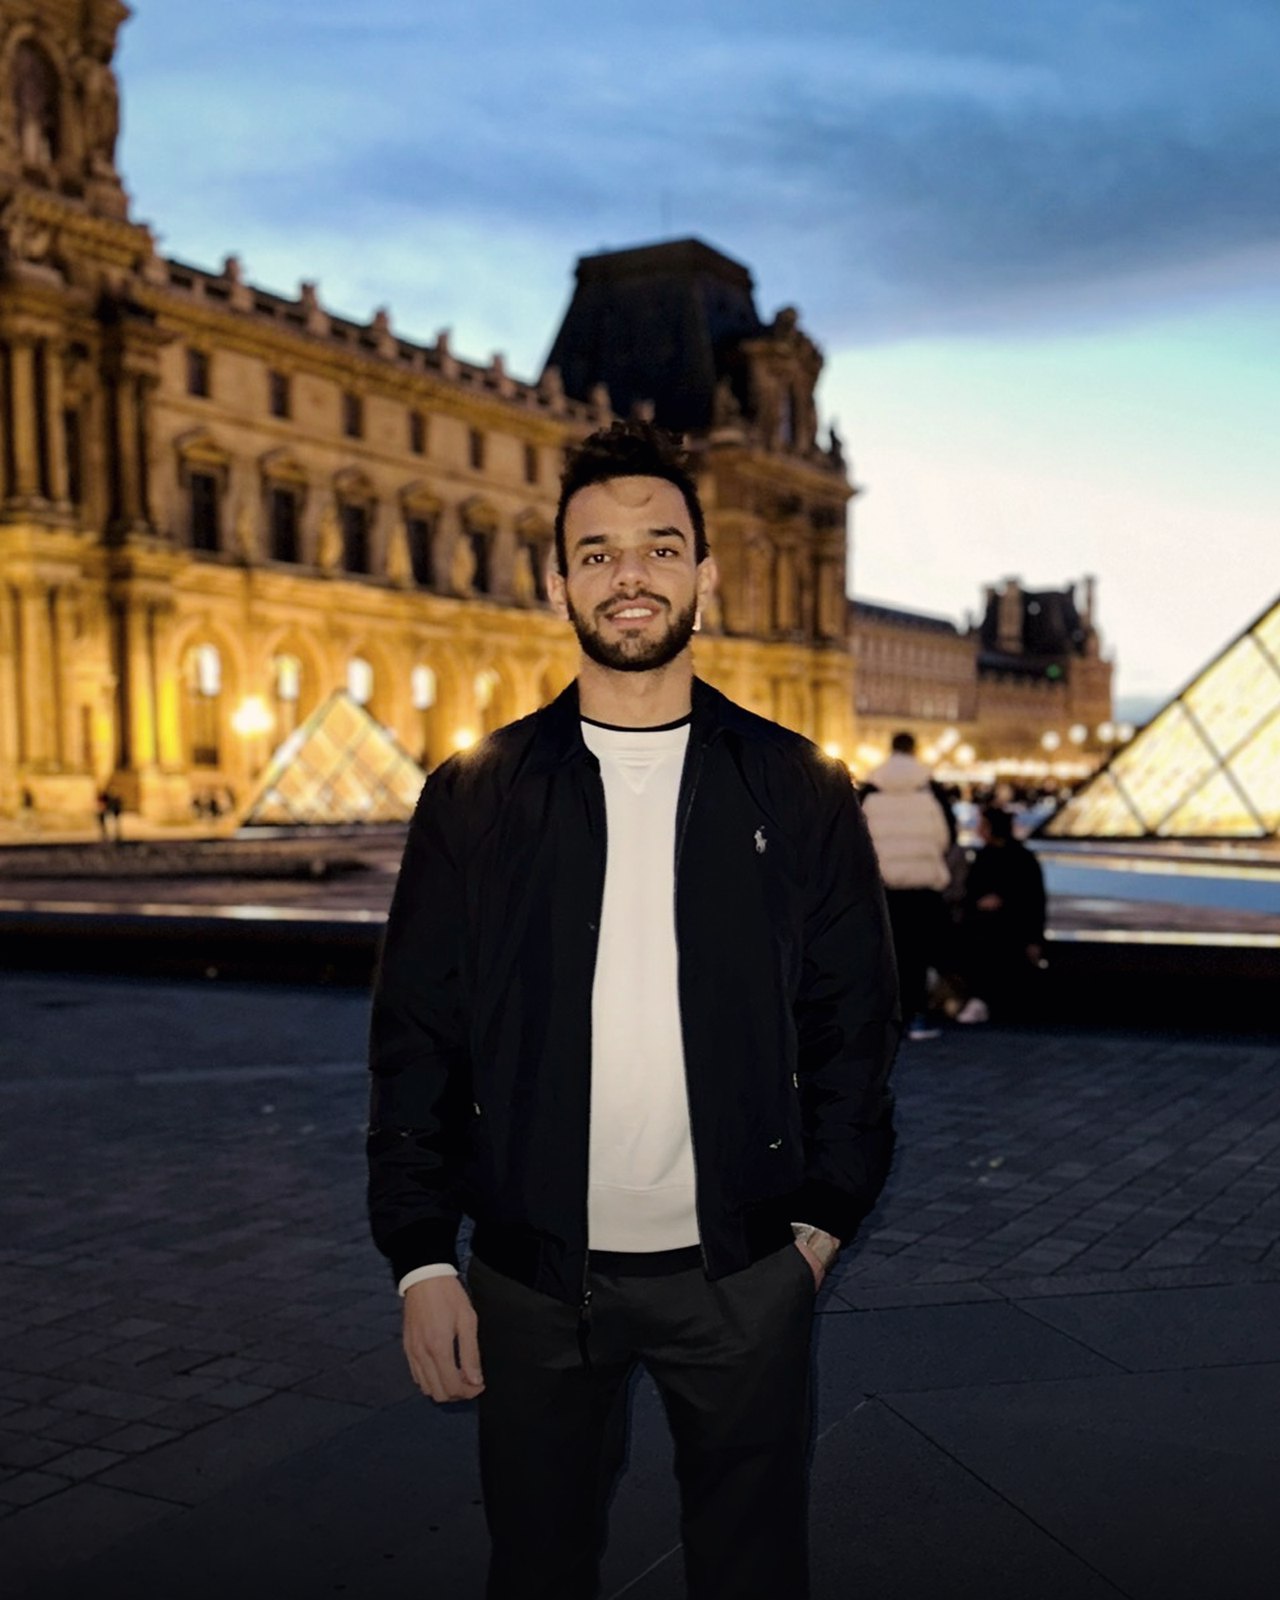
Mateen works on AI systems that make decisions at scale, mostly in Trust & Safety and large platform operations. He decides how those systems are tested and governed before they are trusted with real decisions.
Today he sets the standard for how prompts are written and tested. He also builds the evaluations that decide when a model is ready to ship.
He has moved advanced AI research into production and led a global team of 30 annotators.
What connects all of it is a habit of measuring an AI system before anyone relies on it.
- 30+
- annotators led
- 5
- years in AI Trust and Safety
Areas of work
01
Evaluation frameworks
He builds the tests that decide whether a generative AI system is ready for production. They start from a representative sample and measure precision and recall separately, because the two kinds of error rarely cost the same. After launch, regression tests and drift monitoring show whether the system is still behaving.
02
AI governance and operating models
He writes the governance rules that follow an AI system from its first version into production. They set out who may change a model and who signs off before it reaches users, with clear ownership across product, engineering, data science and operations.
03
Prompt architecture
He sets the standard for how prompts are designed, turning complicated requirements into model behaviour that can be tested. He treats a prompt as a specification, which means it gets measured like one.
04
Data and annotation operations
He has run the operations behind generative AI models, leading more than 30 annotators and overseeing training from data selection through to fine-tuning, with quality checks that kept the labels reliable.
05
Agentic AI under human oversight
He designs AI agents that work within written guidelines and pass uncertain or high-stakes decisions to a person. Much of the work is deciding where that person sits and how their corrections improve the next round of evaluation.
Perspectives
Perspective 01
On metrics
Every AI project should begin with the decision it is meant to support and a written definition of what a correct one looks like. Once that definition exists, everything else becomes measurable. The team knows which examples to sample, which errors are expensive and what precision and recall the system has to reach before anyone trusts it. The model is then a candidate to be judged against that standard.
Perspective 02
On ground truth
Keep the ground-truth set small and made of real examples, then re-run it after every prompt change. Prompts and models keep changing underneath you. Re-running the same set after each change is how the quiet failures get caught, which only works if the set stays small enough that nobody skips it.
Perspective 03
On oversight
Human oversight belongs in the design from the first day. It decides which decisions the model may make on its own and which ones it must hand to a person. It also decides how confidence is expressed and what happens to a correction once someone makes one. At scale the design question is where people sit in the loop and whether the loop is fast enough to matter. The people in that loop see what the model gets wrong before any metric does, so their time should go where the model is weakest.
Model training
Training a generative-AI model well is a loop. Every round of evaluation shows what to collect, label and fine-tune next.
Hover or tap a step to see what happens there.
01
Data selection
The model learns from real examples, sampled to match the decisions it will face in production.
02
Preprocessing
The data is cleaned and structured so each label matches exactly what the model will see.
03
Fine-tuning
Fine-tuning turns the labelled data into model behaviour.
04
Evaluation
The model is tested for accuracy, efficiency and bias against held-out ground truth before anything ships.
05
Retraining
The evaluation results decide what the next round of retraining focuses on.
Agentic AI
An agent is a model that can take actions. Whether it can be trusted depends on the system built around it, which decides what the agent may do alone, when it hands over to a person and how every outcome gets measured. The diagram shows the general pattern used across the industry.
Hover or tap a step to see what happens there.
01
Requirements become prompt architecture
The written requirements become prompts with precise, testable behaviour. Each version is approved like a specification.
02
The agent and its tools
The model works with retrieval, classifiers and tools to reach a decision and a measure of how confident it is.
03
Take the action, or hand it to a person
Confident, low-stakes decisions are actioned by the agent. Uncertain or high-stakes decisions go to a person and that person's correction becomes new data for the system.
04
Every decision feeds back into the system
Every decision is monitored and evaluated. What the evaluation finds flows back into the requirements and the prompts.
Building
Mateen is building a set of agents on one architecture. The first handles Irish admin, where not knowing a rule quietly costs people money. It finds the tax credits nobody claimed and works out what a person can really borrow, then prepares the paperwork for them to submit.
Tap any point to see what it is.
01
One architecture, many domains
Every agent runs the same six stages, so the only thing that changes between them is the domain. It reads the person's documents and looks up the rules, then does the arithmetic in code so that no figure depends on a model remembering it.
02
The person stays in the loop
The agent reads, calculates and drafts on its own. Anything that would submit, send, book or pay waits for the person's approval, with any change they make kept as data.
03
Every figure has a source
Rules live in tables where each figure carries its source and the date it was checked. A figure without one fails the tests, so nothing rests on a model's recollection.
04
Everything is measured
A fixed set of worked examples runs against the live site and scores each answer for whether the decision was right and whether every figure can be traced back. The score gets published, including the runs that went badly.
Selected work
01
ireland.mateenrahmat.com, 2026
Ireland agent stack
He built a set of agents for Irish admin that covers mortgages, tax, renting, immigration and health on one shared architecture. Each agent reads the person's documents and looks up a rule table where every figure carries its source and checked date, then does the arithmetic in code before drafting what needs doing. Anything that would submit, send, book or pay waits in an approvals inbox for the person, with their changes kept as labelled data. Every run ends in one structured decision that is traced beside the conversation.
ResultIt shows agents working under human oversight, with a fixed evaluation that plays every worked example against production and scores whether each decision was right and each figure can be traced.
- Agents
- Evaluation
- Human oversight
- Cloudflare Workers
- Claude
02
Personal site, 2026
Mateen's AI on this site
He built an assistant that answers only from written sources, which are the CV as numbered facts and a notes file. Every claim carries a citation that jumps to its source, private topics are declined and a fixed eval checks its behaviour before every deploy.
ResultEvery statement about Mateen on this page can be traced to a source and the assistant says when it cannot.
- Claude
- Cloudflare Workers
- Evaluation
03
University College Dublin, MSc project
Explainable financial forecasting platform
For his MSc he planned and built a forecasting platform where every prediction comes with an explanation a non-specialist can act on.
ResultThe system was judged on its accuracy and on whether its reasoning could be inspected.
- Explainability
- Forecasting
- Python
Experience
May 2026 to Present
Dublin
Staff AI Evaluation Engineer
LinkedIn·He leads how generative AI is tested and governed before it is trusted with high-stakes decisions.
- 01Shapes how AI agents are adopted and scaled for high-stakes decisions, working with senior leadership on priorities.
- 02Leads generative-AI oversight from design through validation to production.
- 03Builds the evaluation frameworks that decide whether generative AI is ready for production.
- 04Sets governance standards for AI in production, covering versioning, approvals and decision rights.
- 05Sets the technical standard for prompt design, turning complex requirements into precise, testable model behaviour.
Apr 2025 to Apr 2026
Dublin
Senior GenAI Project Manager
Meta·He took generative-AI research into production and ran the data operation behind it.
- 01Oversaw training pipelines for generative-AI models end to end.
- 02Led and mentored a team of more than 30 data annotators producing high-quality labelled datasets.
- 03Defined and tracked the metrics used to judge model accuracy, efficiency and bias.
- 04Partnered with engineering, research and product teams on generative-AI initiatives.
- 05Managed several AI and machine-learning initiatives at once, from concept to deployment.
- 06Drove experimentation with LLM applications and AI-powered productivity tools.
Sep 2021 to Mar 2025
Dublin
Risk Prevention Specialist
Meta·He did data-driven risk prevention for three and a half years, which is where the habit of measuring something before trusting it started.
- 01Analysed large-scale datasets with SQL and Python to find the patterns behind product improvements.
- 02Delivered data-backed recommendations to leadership and cross-functional partners.
- 03Planned and implemented AI-assisted monitoring that improved detection accuracy and reduced false positives.
- 04Managed end-to-end projects across AI, data and risk.
Education
2024 to 2026
MSc, Data Science and AI
University College Dublin
2017 to 2020
BSc, Information Technology (Data Science)
American University of AfghanistanCum Laude
Languages
English (fluent) and Dari (native)
Skills
AI
- Prompt engineering (zero-shot, few-shot, hybrid, RAG)
- AI agents & assistants
- Human-centric AI
- AI ethics
- Fine-tuning data curation & annotation
Evaluation & Governance
- Ground-truth dataset design
- Sampling methodology
- Precision and recall analysis
- Error taxonomies
- Regression testing
- Drift monitoring
- Versioning & approval pathways
Product & Program
- Cross-functional leadership
- Stakeholder partnership
- Leading global teams
- Operational strategy
Programming
- Python
- Java
- SQL
- R
- MATLAB
Data & Analytics
- Statistical analysis
- Data cleaning & modelling
- Data ethics
- Tableau
- Power BI
- SAP BusinessObjects
Trust & Safety
- Platform integrity
- Crisis management
- Risk prevention & anti-abuse
- Content review & enforcement
Contact
Happy to connect.